← Home

MSC AI & DATA SCIENCE / MODULE 07

Data Engineering

Extracting, cleaning and enriching data; relational and non-relational sources; pipeline design, monitoring and production readiness.

THE PRACTICE BEHIND THE MODULE

What I take into the work

A useful pipeline makes data quality, lineage, refresh and failure visible to its owner before anyone relies on the output. Ideally, it should not require its author to stand beside it looking hopeful.

Extracting, cleaning and enriching data; relational and non-relational sources; pipeline design, monitoring and production readiness.

FROM THE SOURCE REFLECTION

Course reflection

My account of the learning and its application, distilled from my combined course reflection. The original document is held privately.

  1. Relational modelling and SQL established how keys, joins and data definitions affect the trustworthiness of a product.
  2. Python with database access and pandas connected extraction to cleaning, transformation and reproducible outputs; later study examined pipeline architecture, deployment and monitoring.
  3. I use these ideas to design for lineage and failure handling. The synthetic staff-survey pipeline is a design exercise, while the separate real student-survey preparation is a completed descriptive workflow, not a production pipeline.

About the code: Python code and notebooks for the coded studies are privately stored and maintained by me. I’m happy to answer questions about the methods and their limits; any sharing of an artefact would depend on the permissions and data involved.

MILESTONES IN PRACTICE

From method to judgment

Three steps show how the learning moved into an artefact or decision, and where the evidence stops.

01

Model

Use relational keys, SQL and Python to reason about clean, linked data.

02

Prepare

Harmonise real but restricted survey exports for descriptive comparison.

03

Design

Rehearse scheduling and monitoring with a synthetic staff-survey schema; deployment remains unclaimed.

SELECTED PORTFOLIO EVIDENCE

Applied studies

Original summaries of my work. Each distinguishes the source, the work's stage and what it can support.

APPLIED STUDY

Staff experience pipeline design

Data basis
Curated synthetic survey schema; no real employee responses
Stage
Academic design exercise; production pipeline not claimed

I scoped a synthetic staff-survey example to reason through extraction, validation, transformation, storage, scheduling and monitoring. The design considers missing values, consistent response scales and aggregate reporting.

Reading the evidence
The synthetic schema rehearses engineering choices. It does not describe an operational staff survey or prove a deployed scheduler, database or monitoring stack.

APPLIED STUDY

Repeatable survey preparation

Data basis
Restricted, real student survey exports
Stage
Completed descriptive analysis; not a production pipeline

A separate applied analysis harmonised several annual feedback exports so comparable themes could be examined consistently.

Reading the evidence
A reproducible preparation workflow is not the same as a continuously deployed data product.

EVIDENCE & PRIVACY

These summaries do not reproduce academic submissions, restricted datasets, individual records, internal systems detail or private course materials. A design, prototype and deployed service are different stages; each study is labelled accordingly.

Seeing where prediction misses

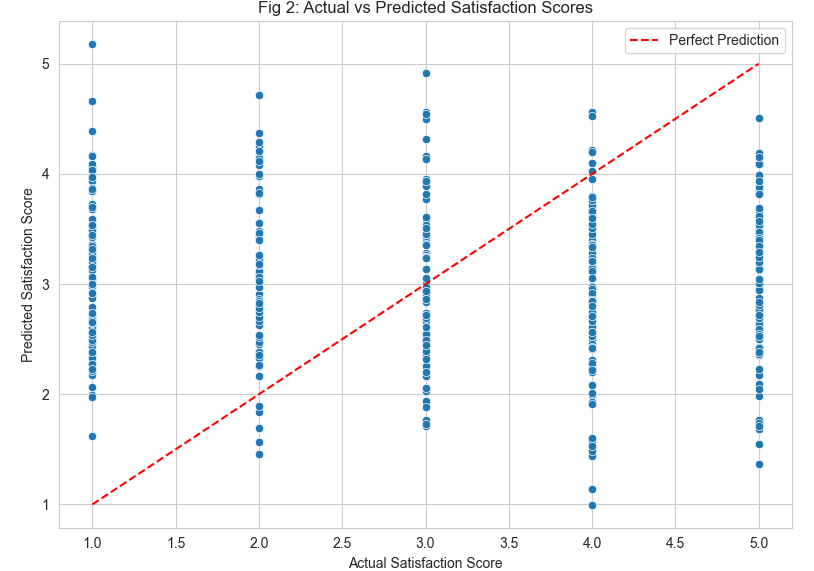
The second Data Engineering study documented a proposed orchestration approach and a synthetic satisfaction model. Its actual-versus-predicted plot is useful precisely because it shows scatter around the ideal line. A polished plot cannot replace temporal validation, error analysis and real-world governance.

Original academic chart comparing actual and predicted satisfaction scores in a synthetic student survey model; points show substantial spread around the ideal line
A diagnostic, not a deployment claim. This original figure in the second Data Engineering report compares predictions with held-out synthetic satisfaction values. The spread around the diagonal is a reason to examine error, target construction and subgroup performance before use with real people.

The synthetic staff-survey notebook provides another distinct exercise: visualisations and widget sketches with simulated sentiment and themes. See the staff exhibits and their provenance ↗

EXPLAINABLE AI & DATA / READ THE METHOD

Connect the learning to the evidence.

Use the categories to distinguish a capability, an algorithm, a Python package and a delivery step. A mention in a module or case study does not mean that capability is running on this page.

Follow the reasoning.

  1. QuestionChoose the decision to support
  2. MethodMatch the task to a suitable approach
  3. TestCompare with appropriate evidence
  4. ExplainState limits and human responsibility

Explore the building blocks.

AI Capability4
AI/Data Concepts1
Data Science Pipeline1
Evaluation & XAI2
Python Package3
Responsible AI1

Number of concepts in this guide, not performance or usage measures.

Explore the explanation matrix · 12 concepts

12 concepts shown

On small screens, scroll the table sideways. “Learning context” explains a related idea; it does not mean that method runs on this page. Deep learning is the standard term for “deep ML”.

Technical termTechnical description / definitionIn plain EnglishHow this page uses it
Machine learning (ML)AI CapabilityMethods that estimate patterns or parameters from examples to support inference on other inputs.Primary reference ↗Learn a pattern from examples, then check whether it helps with new ones.Learning context
ML learns from examples. Read the page-specific methods below to see whether any model runs here.
Deep learningAI CapabilityMachine learning using neural networks with multiple representation-learning layers.Primary reference ↗A layered model learns useful representations; more layers do not guarantee a better answer.Learning context
Deep learning is an AI capability, not a label for every chart. No deep model is implied by this explanation panel.
Natural language processing (NLP)AI CapabilityComputational methods for representing, analysing or generating human language.Primary reference ↗Help a computer work with words, while remembering that context matters.Learning context
Text search, translation, thematic classification and generation are different language tasks; their implementation is identified separately.
Sentiment analysisAI CapabilityA language-analysis task that estimates an expressed attitude, often as polarity or sentiment categories.Primary reference ↗Estimate the tone of words—not the private feelings or personality of their author.Learning context
Sentiment estimates expressed tone. It must not be confused with topic classification or a diagnosis of a person.
Data science pipelineData Science PipelineAn ordered, reproducible sequence for acquiring, validating, preparing, analysing and evaluating data.Primary reference ↗A chain from a question and source to an answer someone can check.Method guide
The learning-to-practice path connects framing, preparation, modelling, evaluation and communication.
Features and labelsAI/Data ConceptsFeatures are model inputs; labels are target values or categories used in supervised learning.Primary reference ↗What the model sees, and the answer it is learning to estimate.Learning context
Projects define relevant input features and any target labels before choosing an estimator.
Held-out evaluationEvaluation & XAIAssessment on examples excluded from fitting and model selection, according to the declared split.Primary reference ↗Keep some answers out of practice so the test means something.Learning context
Unseen and appropriately separated cases help assess whether a learned pattern generalises.
Explanation versus causal proofEvaluation & XAIA model explanation describes selected behaviour or contributions; it does not establish causal effects or full reliability.Primary reference ↗A reason for this output is useful, but it is not proof that the model is right.Responsible use
Explain what was actually done and what the available evidence supports.
NumPyPython PackageA Python library for multidimensional arrays and numerical operations.Primary reference ↗The numerical toolbox behind many Python calculations.Learning context
A numerical Python library; it is not an AI capability or an algorithm by itself.
pandasPython PackageA Python library for labelled tabular data manipulation and analysis.Primary reference ↗A programmable workbench for cleaning and comparing tables.Learning context
A tabular Python library; a useful preparation tool, not a prediction model.
scikit-learnPython PackageA Python library providing estimators, preprocessing tools and model-evaluation utilities.Primary reference ↗A toolkit of models and fairer ways to test them.Learning context
A Python library of algorithms and evaluation tools, distinct from each fitted model.
Human oversight and consentResponsible AIPeople retain appropriate review authority, permission controls and correction routes for data use and outputs.Primary reference ↗Keep someone able to question, correct or stop the result.Responsible use
Decision ownership, permission and correction belong throughout the workflow.
OSL · Olukotun Studios Ltd

Olukotun Studios Ltd · Registered in England and Wales · No. 17537910

LinkedIn ↗